 by
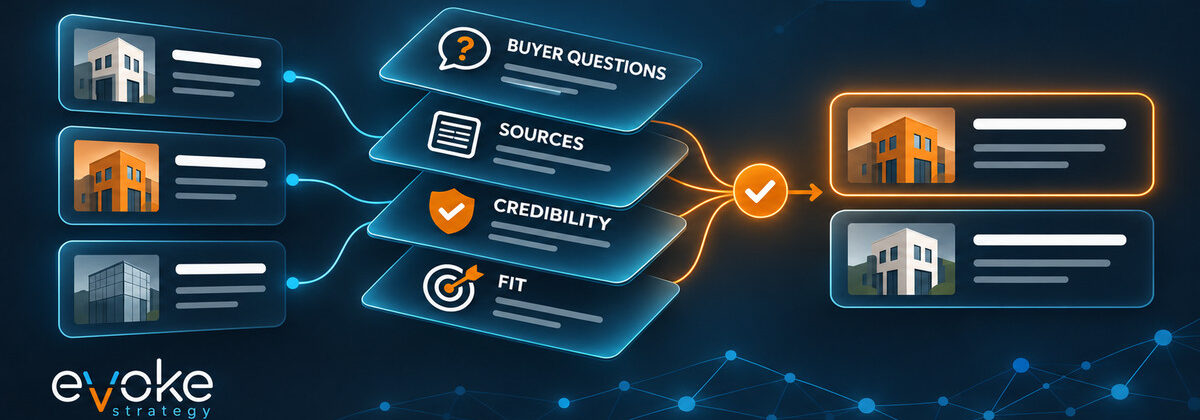
If you want ChatGPT, Google, Claude or Gemini to recommend your business, make it easy to understand what you do, who you help and what makes you a credible choice. Make that information accessible on your own site and supported, where possible, by independent evidence. Then test the questions actual buyers ask. There is no reliable shortcut or guaranteed position in an AI-generated shortlist.
That answer is less glamorous than most of the advice being sold around AI search. It’s also grounded in what we’ve observed in our Florida AI visibility research, including two anonymized research case studies comparing Tampa dental practices and Florida impact-window manufacturers.
AI recommendations can change with the wording of a question, the platform, or simply when you ask. Why does one company make the list and another doesn’t? Ask Sam Altman. We’d be curious to hear his answer. But we can still learn quite a bit from the outside. We can see which companies appear, how closely they match the question, which sources are cited, and where the supporting evidence is strong or thin. That doesn’t give us a formula, but it does give us patterns worth investigating and things businesses can actually improve.
Start with the buyer’s question, not the technology
Most businesses start by asking, “Does ChatGPT know who we are?” A more useful question is, “Would we make sense as a recommendation when a real buyer describes what they need?” Those are not quite the same thing.
Two categories from those research case studies make the distinction clearer: Tampa dental practices and Florida impact-window manufacturers. Someone looking for a dentist may care about location, treatment fit, patient experience and recommendations from other people. A contractor sourcing impact windows is more likely to care about specifications, code approvals, manufacturing capabilities and dealer access. We’ll come back to what AI recommended in both categories, but one generic playbook won’t serve those buyers equally well.
Start with the questions buyers actually ask during a decision: Who handles this kind of project? Which providers serve my market? What is different about these options? What proof should I look for? Your sales conversations, proposals, search queries and customer questions are better starting points than a list of fashionable AI prompts.
Our larger Florida AI Visibility study found that the businesses named in recommendations changed with question wording and platform. That is why we treat a single successful prompt as a data point rather than a ranking.
Being found, being cited and being recommended are different things
An AI system may retrieve a company’s website without recommending the company. It may mention a business in an explanation without including it in a shortlist. It may recommend a company while citing a dealer, review site or trade publication instead of the company website. And someone can see a recommendation without ever clicking through.
For our research, “recommended” means the business actually appeared as a named option in an answer to a buyer-oriented question. “Cited” refers to a page or source linked or referenced in the response. Neither is the same thing as a qualified inquiry or sale.
Those distinctions matter. If an answer retrieved your product page but favored somebody else, the problem may be relevance, differentiation, evidence or simply the variation of one response. Counting retrieved URLs alone would miss it.
Use the Four Cs to improve what buyers and AI can verify
We’ve written about the Four Cs of durable AI visibility before. They’re not Google’s or OpenAI’s published ranking formula. They’re a practical way to look at how a business is represented and supported across the web, whether a buyer finds it through AI search or somewhere else.
Clarity
Can buyers tell exactly when to choose you?
Be specific about what you offer, who you serve, where you work and the situations where you’re a good fit.
Consistency
Does that story hold together across the web?
Your website, business profiles and other credible references should agree on the important facts.
Credibility
Who else can support your claims?
Reviews, real work, qualifications, product approvals and earned reporting can give buyers something independent to check.
Coverage
Is the evidence available where buyers look?
Make useful, accurate information accessible in relevant places. Being everywhere isn’t the goal.
This connects ordinary SEO, content, reputation and PR work. AI search changes how the information may be assembled into an answer; it doesn’t make those disciplines disappear.
What we saw in two anonymized research case studies
The two categories we mentioned earlier give us a way to see this in practice. We tested buyer-oriented questions about Tampa dental practices and Florida impact-window manufacturers, then compared which businesses appeared and the publicly available evidence surrounding them. These are anonymized research case studies from Evoke’s own observations, not client success stories or proof that any particular factor caused a recommendation. The point is to examine the patterns and their limits, not publish a scorecard on somebody else’s business.
Case study 1: Tampa dental practices and changing AI recommendations
In an earlier Tampa general-dentist study, Practice A was named in 33 of 96 AI recommendation runs. A comparable Practice B appeared in none. When we later examined their public footprints, Practice A had a substantially larger Google review volume and more sustained local community discussion. Practice B, meanwhile, ranked for more organic search keywords in the research snapshot.
| Observed measure | Practice A | Practice B |
|---|---|---|
| Historical recommendations | 33 / 96 | 0 / 96 |
| Google reviews, recorded snapshot | About 4,125 | About 482–487 |
| Estimated ranking organic keywords | 154 | 373 |
It is tempting to point to the reviews and declare the mystery solved. We can’t do that. The practices differed in other ways, and we did not isolate the effect of reviews, community mentions or any other input.
The reviews and community discussion are worth investigating, not because we’ve proven they caused the earlier gap, but because they may help explain why the two practices were represented differently. None of this tells us which practice provides better care.
Case study 2: Florida impact-window manufacturers across four AI models
We also tested a Florida impact-window and door buyer question on September 7, 2026, using ChatGPT, Claude, Gemini and Perplexity. All three manufacturers were relevant to the category. One appeared in all four final shortlists, a second in two, and the third in none. The company absent from the final shortlists had considerably more ranking organic keywords in the associated SEO snapshot than the manufacturer selected by every model.
One buyer question. Four AI models.
Which manufacturers appeared in each final recommendation list?
| Manufacturer | ChatGPT | Claude | Gemini | Perplexity | Total |
|---|---|---|---|---|---|
| Manufacturer A | ✓ Yes | ✓ Yes | ✓ Yes | ✓ Yes | 4 / 4 |
| Manufacturer B | — No | — No | ✓ Yes | ✓ Yes | 2 / 4 |
| Manufacturer C | — No | — No | — No | — No | 0 / 4 |
The SEO comparison: Manufacturer C had 3,326 estimated ranking organic keywords in our research snapshot, compared with 1,341 for Manufacturer A. That difference did not predict which appeared in these four responses.
What stood out: Being found isn’t the same as being recommended. One model retrieved Manufacturer C but left it off its final shortlist.
The models relied on different combinations of company pages, dealer information and evidence about Florida manufacturing, impact products and relevant approvals. That gives us something more useful to investigate than a raw count of brand mentions.
Again, this is not evidence that organic rankings don’t matter, or that a particular source forced the models’ choices. Four responses are a starting point, not a stable market share of recommendations. What they show is why exact buyer fit and source context are worth examining alongside conventional SEO metrics.
What we’d actually do to improve your AI Search Visibility
If a business isn’t showing up when buyers ask AI for recommendations, we don’t start by chasing a trick or writing another stack of near-identical articles. We work through a repeatable process: understand the buyer’s questions, test what AI recommends, examine the evidence, identify worthwhile improvements and measure again. Our free audit offers an initial snapshot; a deeper assessment lets us investigate the full picture.
- Map the questions buyers actually ask. We start with real customer inquiries and sales conversations, then check that language against search behavior and related buyer questions. For a deeper review, we build a focused set of questions covering general discovery, specific needs, comparisons and credibility checks. We account for the buyer, category and service area, rather than testing ten variations of “best company.”
- Test the questions and compare the answers. We look across the AI platforms that matter to the market, recording which businesses are recommended, where your company appears or is missing, and which sources get cited. We compare results by question and competitor, rather than treating one favorable answer as a permanent ranking.
- Check your website and technical foundations. Can a buyer quickly understand your capabilities, service area, ideal customer, limitations and reasons to choose you? Do important facts agree across your site and reputable profiles? We also inspect whether the relevant pages are accessible to search systems, supported by appropriate structured information and written clearly enough to use.
- Examine the evidence around the companies being recommended. Look at what their own sites say and what independent sources support: real reviews, industry credentials, product approvals, case studies, expert commentary and earned coverage. These comparisons help us spot gaps worth investigating; they don’t prove any one source caused a model to recommend a company.
- Choose improvements that address a real gap. That might mean clarifying a service page, correcting inconsistent company details, making technical information easier to find, publishing stronger examples or earning relevant third-party coverage. The right response depends on what the buyer needs and what the evidence shows, not a generic list of AI-search hacks.
- Make the work useful beyond AI search. Stronger product information, trustworthy reviews, accurate profiles and better answers to buyer questions also help people evaluating the business directly. We don’t need to manufacture endorsements or fill low-quality directories to make progress.
- Measure again, and connect visibility to actual business activity. Repeat a consistent set of relevant questions over time, recording the platforms, dates, recommendations and cited sources. Then look for changes alongside qualified visits, inquiries and sales conversations. AI results move around, and a rise in mentions alone isn’t proof of growth.
Why we wouldn’t chase the usual AI-search hacks
There is a difference between making information easier for systems to access and trying to manufacture the appearance of being recommended. The former is sensible marketing. The latter is where the shortcuts get questionable.
Clear information, verifiable claims, authentic customer proof and relevant independent coverage.
Self-awarded “best” rankings, fabricated proof and paid endorsements disguised as independent recommendations.
Sponsorship and paid distribution have legitimate roles. The problem is presenting paid placement as independent approval.
Likewise, it is worth keeping the technical claims in perspective. Google explicitly says there is no special AI-specific schema or extra AI text file required for its AI features. Structured data can still help with ordinary search features when it accurately represents visible content. Neither that nor a particular page format comes with a promise of AI citations or recommendations.
Some tactical experiments may eventually prove useful, and platforms will keep changing. We should test meaningful changes rather than dismiss every new idea. But a tactic deserves more than a screenshot of one favorable answer before it becomes a company-wide recommendation.
Measure the shortlist, then measure the business
A useful AI-search report can show which relevant questions produced a recommendation, which competitors appeared and which source pages were cited. It should also say how many runs were tested, on which dates, and where the models disagreed. That gives you a starting point for investigating the gaps.
Which buyer questions produced a shortlist, and who appeared?
Which cited pages, evidence and competitors showed up in the answers?
Are qualified visits, inquiries and sales conversations changing?
Then bring the discussion back to marketing outcomes. Did qualified people visit? Are they searching for the business by name? Are the conversations better informed? Can a sales team point to opportunities that began with a recommendation? Not every path will be directly attributable to AI, and a sudden bump in mentions is not the same as growth.
The way we look at it is familiar: build authority, increase visibility, create demand and measure impact. AI search is an important place where visibility can happen, but it should be connected to those other stages rather than treated as a separate scoreboard.
The useful goal isn’t to win one AI answer
You cannot guarantee that an AI platform will recommend your business, or that today’s answer will look the same next month. You can make your business easier to understand, give buyers better evidence for choosing it and improve the odds that relevant information is available when a question comes up.
That work is useful even if one particular model never cites you. It helps the customer make a better decision, which is a more durable place to start.
Research methodology and limitations
These are anonymized research case studies from Evoke Strategy’s internal AI visibility work, not client success stories or evidence that an optimization campaign changed recommendations. The Tampa dentist figures are from an earlier metro recommendation study of 96 recorded runs per practice; the later Google-review and SEO counts came from separate public-data research snapshots. In a September 7, 2026 exact-question rerun, ChatGPT, Gemini and Perplexity provided named lists that included neither practice; Claude declined to give a comparable shortlist.
The Florida impact-window comparison used one buyer-oriented prompt across four models on September 7, 2026: ChatGPT, Claude, Gemini and Perplexity. “Shortlisted” means named in the final recommendation answer, not merely retrieved or cited. SEO metrics and public-source observations were collected separately. Different runs, prompts, geographies, system versions and dates can produce different outcomes. We have not demonstrated causality between any source type and a recommendation, and the anonymized examples are not independently replicable from the names printed here.
For wider context, see our Florida AI Visibility study and our article on the Four Cs. For technical guidance, see Google Search Central’s documentation on AI features and OpenAI’s crawler documentation.